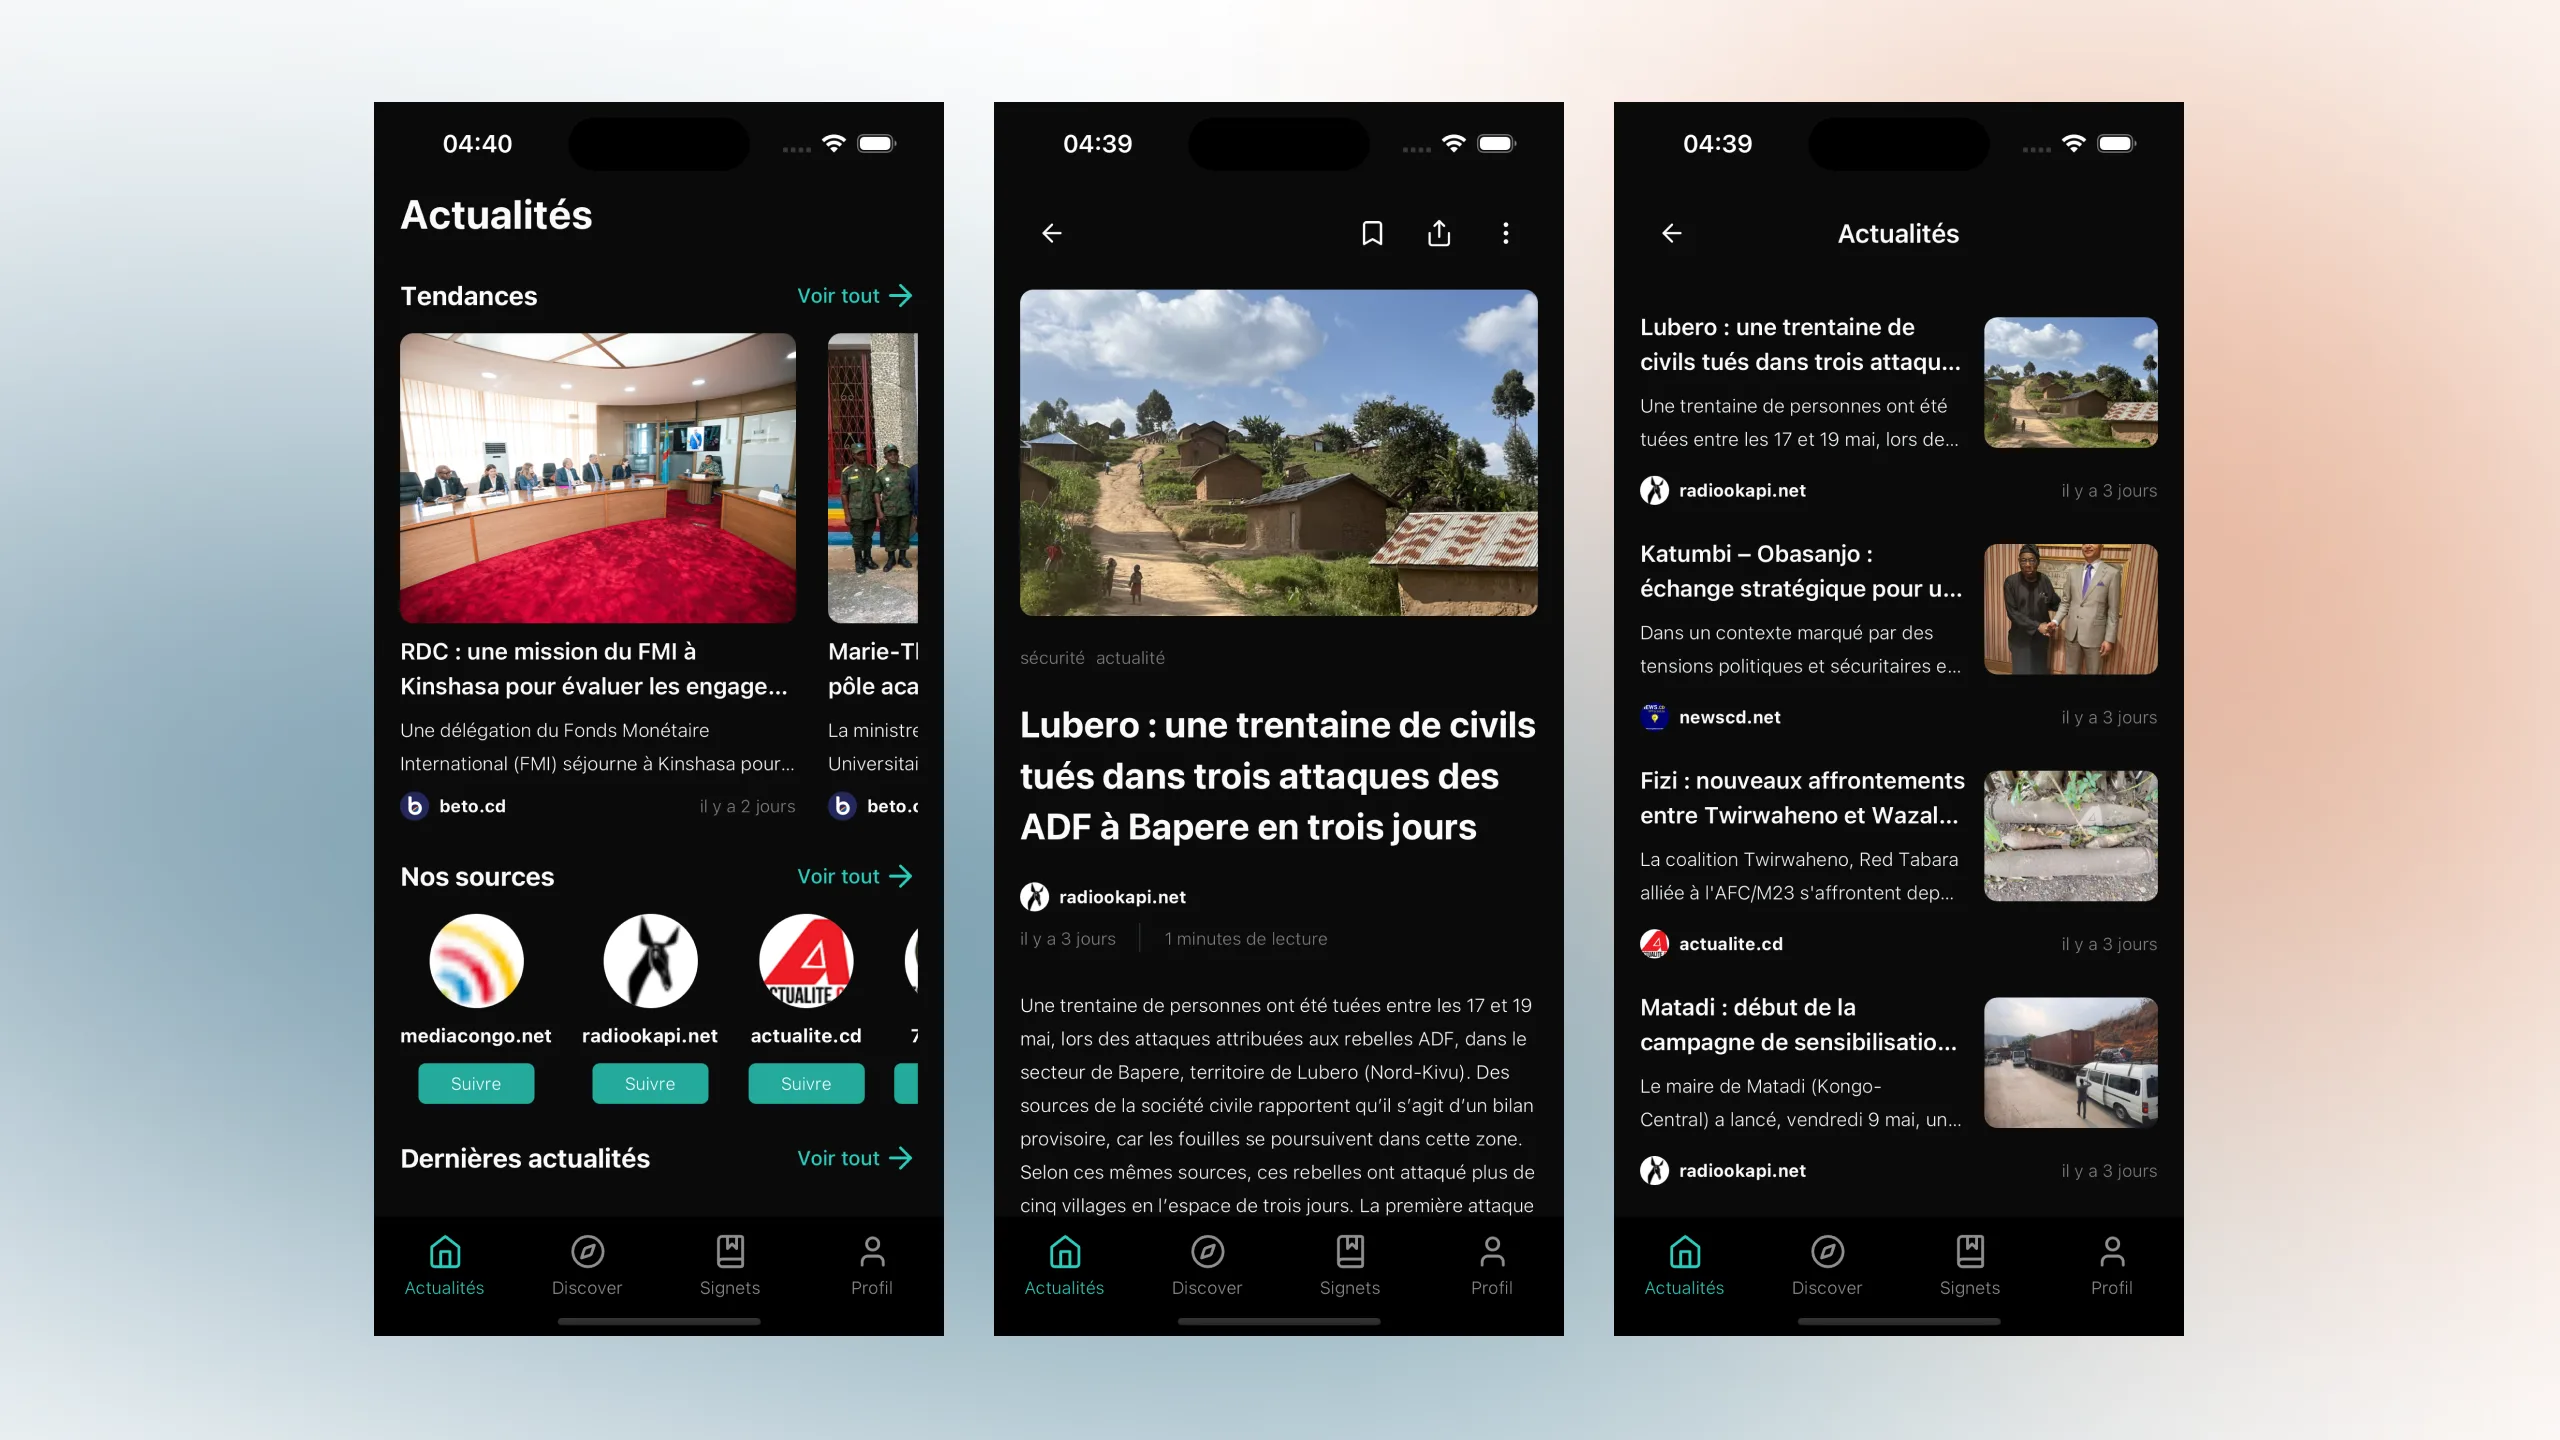
I started Basango because following the war and security situation in eastern DRC meant checking many sources by hand. Reports were spread across websites with different categories, date formats and ways of publishing. Once an article left a site's front page, finding it again could take another search.
I built a shared collection of these articles, keeping the publisher, original link, publication date and extracted content. The aim is to spend less time gathering reports and more time comparing them. The collection also provides material for later analysis, although inclusion in Basango does not verify an article's claims or its publisher's credibility.
The first implementation used a TypeScript crawler, local JSONL files and a Next.js dashboard. I have since separated the crawler into a Rust application and moved the dashboard to TanStack Start. The more substantial change is how the system records unfinished work: an article can now wait locally for delivery, and an accepted article can wait in PostgreSQL for search indexing.
Basango Crawler handles collection. It extracts and normalizes articles, saves them in SQLite, then sends them to the API. It runs independently of the Bun workspace in Basango, which contains the Hono API, dashboard, mobile reader and shared packages.
Within that application, PostgreSQL holds the reference copy of each article. Meilisearch holds a searchable copy that can be rebuilt. The TanStack Start dashboard and Expo reader access the data through tRPC; MCP clients have a separate read-only interface. Drizzle ORM handles the application's PostgreSQL persistence.
The diagram below follows article data through the implemented system. Worker queues and monitoring have separate roles, described later.
Mermaid
The HTTP boundary lets the crawler deliver articles without direct database access. In turn, the clients use validated API contracts rather than importing the persistence layer. A failed request at either boundary needs to be recoverable without repeating the entire collection process.
I maintain a configuration for 30 sources: 6 HTML sources and 24 WordPress sources. Availability and archive coverage still need to be measured for each source.
HTML sources declare selectors for listing items, article links, titles, bodies, dates and pagination. WordPress sources use structured REST responses. Both adapters produce article drafts that pass through the same normalization step.
Four sources declare indexed categories and require a crawl for each category. Page ranges, date ranges and forward or backward collection let an operator target updates or older archives. Publication boundaries can be requested from the API, including boundaries scoped to a crawler category.
Configuration validation rejects duplicate source identifiers, conflicting queue names and inconsistent category pagination settings. Source-specific selectors and pagination rules stay in configuration, while the execution pipeline is shared.
Normalization rejects empty titles and bodies, cleans invisible characters and whitespace, and removes repeated category labels without treating capitalization as a difference. Each article keeps its source identifier, URL, publication date and available metadata.
The crawler computes an MD5 hash of the article URL as a stable identity. Here, the hash supports repeatable storage and delivery; it is not a security mechanism. Two copies of the same story at different URLs remain separate records.
I use direct crawling to inspect extraction and run one-time collections. For background work, the executable also supports Redis queues through the Rust BullMQ client. Tokio provides the asynchronous runtime; Reqwest handles HTTP requests; the HTML adapter uses Scraper.
Queued work has three stages:
Discovery finds article candidates from listing pages or API responses.
Article processing extracts and normalizes content, then saves it locally.
Delivery reads the saved article and sends it to Basango's ingestion API.
Redis queues are scoped to an agent identifier. Each machine needs its own identifier because delivery jobs refer to articles in that agent's local SQLite database. A delivery job therefore needs to reach the agent that holds its article, even when several agents run alongside one another.
HTTP requests have timeouts, bounded retries and backoff, with support for Retry-After. Source settings can require rate limiting. These controls help handle temporary failures, but changed HTML selectors still require maintenance.
An extracted article still needs to survive an unavailable API or a worker restart. I replaced JSONL with a SQLite working store that records article payloads, delivery status, attempts and errors. The worker saves an article before enqueueing its delivery. It also records the intent to send it, so an interrupted handoff to Redis can be retried.
Mermaid
A delivery job can retry an API request without fetching the publisher's page again. Entries already marked as forwarded are recognized when a job is repeated. This also covers the case where the API saved an article but its response never reached the crawler: the next request resolves to the existing article.
This design still depends on preserving the agent's local SQLite data. Redis schedules work; it does not replace the saved article payloads.
The crawler has Linux release archives for x86-64 and ARM64, including a deployment path for Raspberry Pi 5. A systemd service manages the worker process. Scheduling remains an explicit CLI or cron responsibility.
Graceful shutdown drains active work and leaves incomplete runs available for recovery. Repeated Redis connection failures cause the worker to exit so systemd can restart it. The CLI also exposes source synchronization, queue and outbox status, and manual delivery retries.
The Rust crawler can be deployed as a native executable independently of the web application. That deployment change is established; I have not published a speed or memory comparison with the earlier TypeScript version.
A retry leaves an important ambiguity: the API may have saved an article even if the crawler never received the response. I handle that ambiguity at the ingestion endpoint. Article ingestion requires a machine credential and an Idempotency-Key matching the URL hash. The API validates that identity and uses PostgreSQL's unique hash constraint with an atomic insert-on-conflict operation.
A repeated request returns the canonical article and indicates that it did not create a new record. This protects against duplicate inserts from retries or overlapping crawls. It does not merge related reports or update the content of an existing article automatically.
The classifier maps normalized publisher category labels to configured Basango categories. Candidate matches contribute weighted scores, deterministic tie-breaking selects a category, and unmatched records receive a fallback category.
I can inspect and edit these mappings through category configuration. The rules operate on publisher labels rather than the meaning of the article body. A missing or misleading publisher label can still lead to a poor assignment, so classification quality needs evaluation against reviewed examples.
PostgreSQL serves article lists and details. Explicit text searches use Meilisearch, whose documents include article, source and category information. That avoids a separate database lookup for every search hit.
Search introduces another delivery step. I record the article and its pending indexing task in the same PostgreSQL transaction, then attempt indexing after commit. A search failure therefore does not invalidate successful article ingestion; the pending update remains available for a later synchronization command.
Full rebuilds scan articles by ID, send batches bounded by payload size to a temporary index, verify document counts, and swap that index into the stable name. The live index is not emptied at the beginning of a rebuild. Changes to source and category display data also mark affected documents for reindexing.
The tradeoff is eventual consistency: an article can be available in PostgreSQL before it appears in search. Search also adds a service to operate and an index to monitor and repair.
The dashboard is where I inspect the collection and its activity. It supports article browsing, source and category management, publication reports, user administration and ingestion monitoring. Tables and charts show the dataset by source, category and publication period.
I moved the web application to TanStack Start with Vite and Nitro. TanStack Router handles routes, access guards, parameters and preloading. Feature modules contain the screens and their interactions, while TanStack Query and tRPC handle server data.
Better Auth manages credentials, sessions and password reset. The dashboard requires the administrator role. The mobile reader shares the identity system without receiving administrative access.
To investigate a crawl, I need to distinguish a discovered link from an article that reached PostgreSQL. The operations screens therefore track discovered, processed, persisted, skipped, delivered and failed articles separately.
The crawler supplies those figures through heartbeats and run lifecycle signals, using stable signal identifiers and absolute counters. The API validates the signals and stores agent, run and activity records. It builds the dashboard's view from those records, so the crawler does not need to know how the screens are arranged.
Mermaid
The ingestion overview receives coalesced SSE notifications that identify which data changed. It then refreshes the corresponding tRPC queries. The event stream is a refresh signal; stored records remain authoritative.
If that overview stream disconnects, the UI reports the connection loss and retains its last snapshot. It reconciles data on reconnect. Separate agent and active-run detail views use timed refreshes. Operational history can be pruned without deleting the article dataset.
The Expo and React Native reader includes article browsing and details, search, source following, bookmark collections and comments. Its native session integration uses SecureStore. It shares domain contracts and the typed API with the dashboard, while keeping navigation and native UI components in the mobile application.
The reader features described here are implemented in the repository. Public app-store availability and user adoption have not been established in this case study.
The API also exposes six read-only MCP tools: list_articles, search_articles, get_article, list_sources, get_source and list_categories. They reuse the reader's data queries and the search service. A dedicated Bearer credential controls MCP access separately from crawler ingestion.
MCP clients can browse or search the collection, then retrieve an article's full stored body and original link. The server instructs clients to preserve source attribution and interpret relative dates in the Africa/Lubumbashi timezone. It does not expose administrative mutations or reader actions such as posting comments.
The recovery mechanisms make it possible to distinguish local persistence, API acceptance and search indexing. They also leave specific work to monitor: articles awaiting delivery on an agent and index updates waiting in PostgreSQL. Increasing worker concurrency alone would not resolve either backlog.
Collection quality needs its own evaluation. I still need to measure coverage across the 30 configured sources, extraction failures, delivery backlog, indexing lag and category accuracy against reviewed examples. Successful runs and high article counts cannot establish completeness or factual reliability.
URL-based identity also leaves the same story at different publishers as separate articles. Cross-publisher story deduplication, semantic search and personalized recommendations remain outside the current implementation described here.